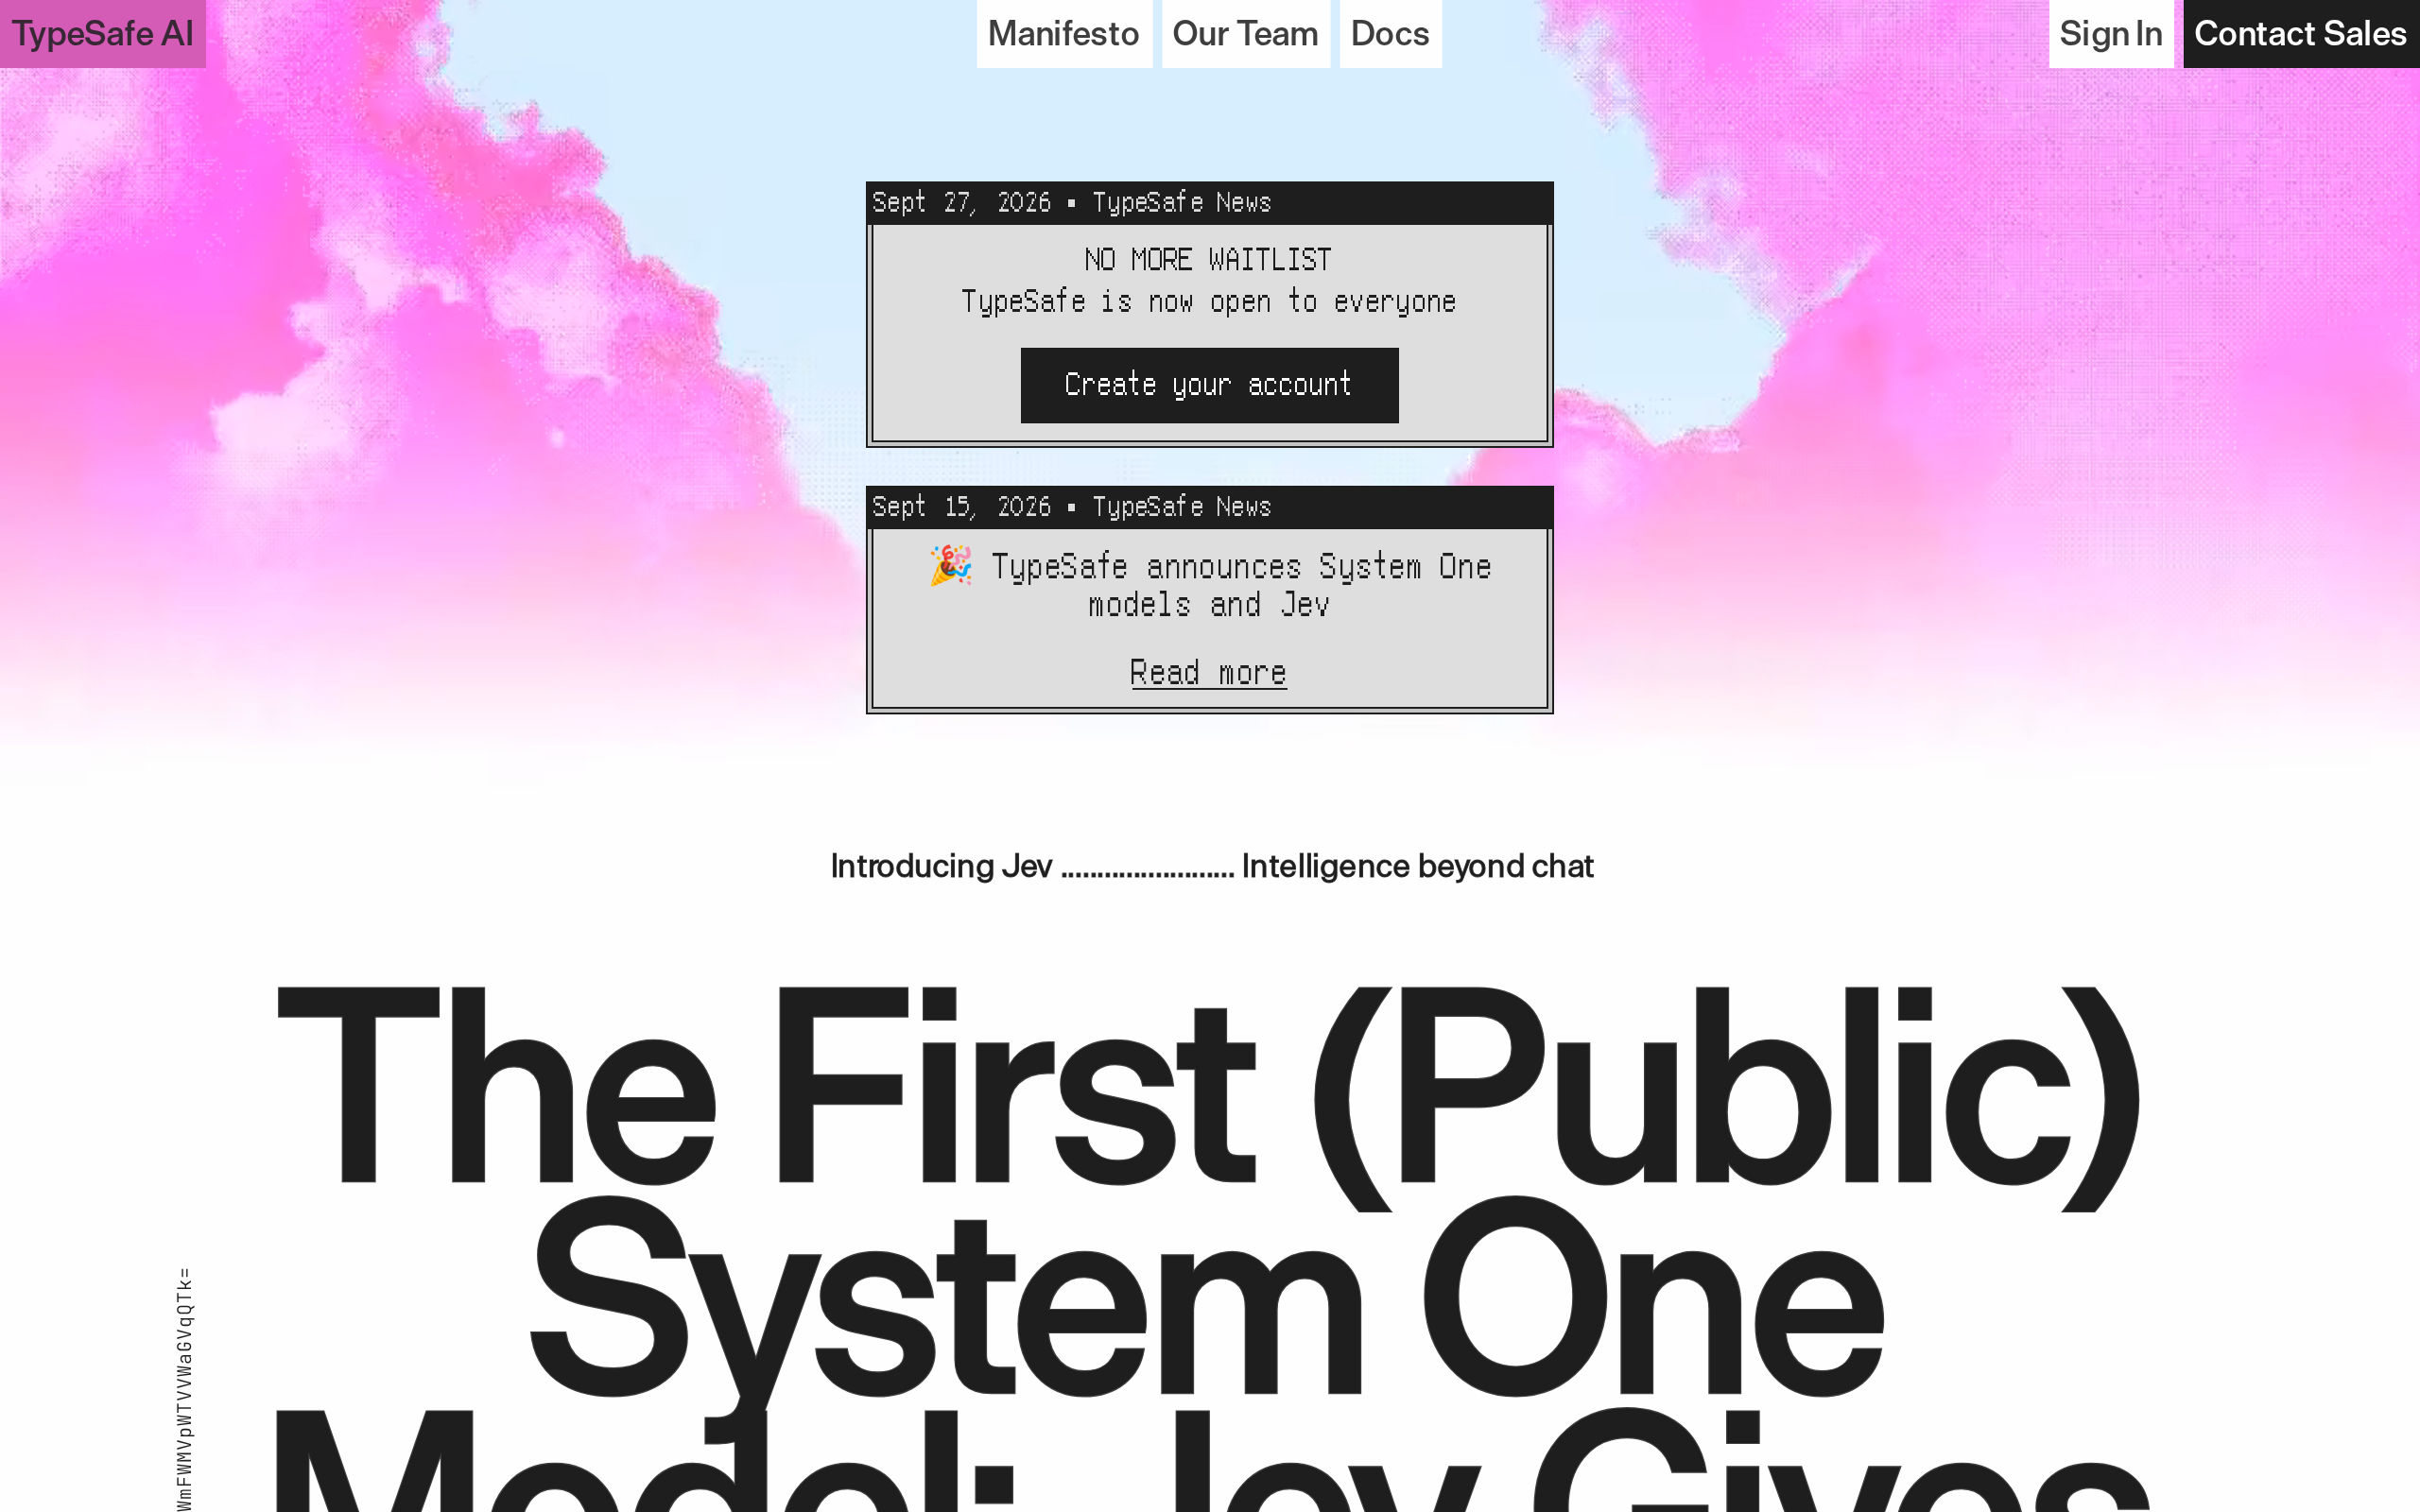
TypeSafe AI built its Jev model to handle operational decisions without generating text. Co-founded by former OpenAI researcher Diogo Almeida, the company released the model on September 15 and opened it to developers on September 21. TypeSafe AI classifies Jev as a 'System One Model'. Company testing claims the engine runs 193.6 times faster than large models at approximately 1/444.6 of the cost, billing input at $0.042 per million tokens with free output.
According to woshipm, LLM researcher Zeng Xiaojian argues that Jev represents an advance in system engineering and product architecture rather than a technical breakthrough. Classifiers and intent recognition models already existed.
The real shift is architectural. Replacing generative prompts with fast evaluators turns an agent's micro-decisions into a concrete decision plane. That structure preserves raw evidence while extracting narrow typed judgments. Yet cheap execution multiplies unreviewed automation unless teams treat probability thresholds and fallback paths as deliberate product policy.
Fast typed decisions repackage classic classification
TypeSafe AI, co-founded by former OpenAI researcher Diogo Almeida, released the Jev model on September 15 and opened it fully to developers on September 21. Instead of generating conversational text or writing code, Jev operates as a System One model dedicated to outputting probability judgments. TypeSafe AI prices the engine at $0.042 per million input tokens while output tokens are free. Official testing reported by woshipm claims Jev runs 193.6 times faster than standard large models at roughly 1/444.6 of the cost.
According to appinn, Almeida stated that Jev represents the shortest path to an AI-based economic revolution. The pitch rests entirely on stripping generative text out of micro-decisions.
Other researchers view the model as disciplined packaging rather than scientific novelty. LLM researcher Zeng Xiaojian argues in woshipm that Jev represents an innovation in system engineering and product architecture rather than a technical breakthrough, because classifiers and intent recognition already existed. LLM researcher Yao Yuhang also noted that the barrier to replicating Jev with fine-tuned open-source models is not high. According to geekpark, a vLLM contributor proved that point one day after launch by matching Jev's preliminary accuracy on Google's DiffusionGemma.
The architecture works because developers stop subsidizing conversational bloat for binary routing. Armin Ronacher, CTO of the Pi framework, argued in geekpark that mainstream large models were heavily subsidized by venture capital, blinding developers to leaner architectural patterns. On suitable tasks, TypeSafe claims speed gains between 20 to 200 times and expense drops between 40 to 400 times. Narrow typed decisions turn expensive inference into a fixed operational budget.
Architectural and Operational Comparison: Fast Decision Models vs. Generative Reasoning LLMs
| Dimension | TypeSafe AI Jev (System One Decision Model) | Traditional / Reasoning Large Language Models |
|---|---|---|
| Primary Functional Role | System One model designed specifically for classification, scoring, and judgment without generating text; functions as an agent's reflex nerve | General slow-thinking reasoning brain designed for conversational text generation and code writing |
| Structured Output Primitives | Choice (candidate selection/routing), Score (continuous rating), and Noul (binary probability between 0 and 1), returning probabilities and confidence scores | Free-form conversational text, code, or natural-language summarization |
| Token Pricing | $0.042 per million input tokens; output tokens are free of charge | Not disclosed in sources |
| Cost for 10,000 Daily Business Decisions | Approximately $120 per month (costs approximately 1/444.6 as much, or 40 to 400 times lower) | Around $35,000 per month (for top reasoning LLMs with equivalent accuracy) |
| Operating Speed | Operates 193.6 times faster (or 20 to 200 times faster); single judgments take tens of milliseconds | Baseline execution speed (not disclosed in sources) |
| Training Methodology | Reinforcement Learning from Calibrated Decisions (RLCD) to align output probabilities with real-world occurrence rates | Reinforcement Learning from Human Feedback (RLHF) |
| Context Management & Auditability | Leaves user and assistant text unedited; uses keepCall and keepResult Noul queries to preserve raw tool calls or truncate results | Traditional natural-language summarization damages auditability by paraphrasing exact technical details like file paths, timeouts, and stack traces |
| Fallback & Product Policy | Pins initial and most recent N messages; falls back to standard LLM summarization if Jev fails or compression savings are insufficient | Not covered in sources |
| Failure Modes & Hallucination | Does not achieve zero hallucinations; can select an incorrect option from among predetermined choices | Not disclosed in sources (traditional summarization paraphrases exact technical details) |
Judgment primitives face the limits of closed candidate sets
TypeSafe AI designed Jev as a System One model that outputs typed probabilistic decisions rather than generating free text. According to appinn and woshipm, its single API call supports three primitives: Choice handles selection among candidate options, and Score provides continuous evaluation. For binary verification, Noul returns probabilities between 0 and 1. By abandoning token-by-token generation, the model trades conversational breadth for immediate verification.
Concrete implementations show how typed decisions work inside real workflows. Geekpark reported that the HA-Jev plugin checks whether washed clothes remain in a washing machine, completing an evaluation in tens of milliseconds for $0.000015. For device control, the Droidrun team built mobile-jev to navigate the Uber application to its payment interface in 9 steps over 21 seconds. On relational data, developers published pg-jev and duckdb-jev on GitHub for probability filtering, while one developer processed 9,081 product-matching records in 13 minutes with a 150-line script, spending $0.32.
Yet closed candidate sets impose a strict ceiling. A system restricted to fixed options cannot invent novel actions when unfamiliar environmental states occur.
That boundary punctures claims that judgment models eliminate generative AI. LLM researcher Yao Yuhang points out that fast decision models suit embodied AI and robotics because robots demand high response speeds, but he notes that Jev still hallucinates by selecting incorrect options from predetermined choices. The woshipm author similarly argues that Jev functions as a reflex nerve rather than a reasoning brain. When options are fully enumerated, probability matching excels. When candidate sets are incomplete, agents must hand control back to slower reasoning models capable of open generation.
Compaction preserves raw evidence where summarization destroys it
Standard context compaction relies on language models summarizing earlier exchanges, but prose rewriting creates operational blind spots. As woshipm's author argues, traditional natural-language LLM summarization damages auditability. Exact technical details vanish when stack traces blur, or when file paths and timeouts lose their precise syntax. An alternative method avoids text generation entirely. Available as an npm library and Claude Code plugin, fast-jev-compaction handles context compression by deciding which tool calls and results to preserve or delete. The tool leaves user text and assistant text unedited. Only paired tool calls and tool results face modification.
Developer Tamara Tran demonstrated this pattern in Claude Code. According to geekpark, her Jev plugin compressed nearly 1 million tokens of context down to 86,000 tokens in 1 second by scoring and filtering historical tool calls.
To make these pruning choices, fast-jev-compaction decomposes context compression into two Jev Noul queries for each tool call: keepCall and keepResult. Based on their probabilities, the system executes one of three actions. It can choose full retention. It can retain the call while truncating the result. Otherwise, it deletes both the call and result. Critical context remains guarded: the initial message and the most recent N messages in conversation history stay pinned and preserved by default. According to appinn, TypeSafe provides an agent skill plugin integrated via Claude Code or an npx command. If Jev fails or compression savings prove insufficient, fast-jev-compaction falls back to standard LLM summarization.
Calibrated probabilities require operational error budgets
According to woshipm, Jev was trained using Reinforcement Learning from Calibrated Decisions (RLCD) to align its output probabilities with real-world occurrence rates. Alongside its decision outputs, Jev returns candidate probabilities and an overall confidence score, as observed by appinn. That statistical grounding encourages teams to treat scores as direct action triggers. geekpark reports that running 10,000 business decisions per day with Jev costs approximately $120 per month, compared to around $35,000 per month when using top reasoning LLMs with equivalent accuracy. Replacing heavy reasoning models with specialized classifiers makes routine routing an affordable background process.
Cheap execution easily outruns oversight. An appinn tester consumed $0.0008 in API credits during an afternoon of testing Jev. That trivial spend makes rapid adoption easy, yet low costs do not protect against misdirected actions.
When judgment costs collapse, throughput multiplies. A single judgment by the HA-Jev plugin takes tens of milliseconds and costs $0.000015, according to geekpark. In one live deployment documented by geekpark, the founder of Distribb used Jev to scan nearly 600 web pages, making 8,790 linking decisions and placing over 500 links within 45 seconds at a total cost of $0.21. Speed magnifies missteps. LLM researcher Yao Yuhang argues, according to woshipm, that Jev does not achieve zero hallucinations because it can still select an incorrect option from among the predetermined choices. Without shadow testing, automated triggers simply scale bad picks.
Decision Plane Architecture: When to Route to Jev vs. Generative Models
- Context window bloat from accumulated tool call logs where preserving auditability and precise technical details is mandatory. Deploy Jev using the Noul binary verification primitive (as implemented in fast-jev-compaction) to evaluate keepCall and keepResult probabilities. Preserve user and assistant text untouched while executing typed actions-retaining, truncating, or deleting paired tool calls and results. Pin the initial message and the most recent N messages, and configure a fallback to traditional LLM summarization only if Jev fails or compression savings are insufficient.
- High-frequency operational micro-decisions, discrete UI navigation, or single-choice routing across predetermined states. Use Jev's Choice or Noul primitives instead of generative reasoning models. This yields latency in the tens of milliseconds and costs $0.042 per million input tokens (with free output tokens), down from an estimated $35,000 per month on top reasoning LLMs to approximately $120 per month for 10,000 daily decisions. Because Jev does not achieve zero hallucinations and can still select an invalid option, consume its returned candidate probabilities and confidence scores to route low-confidence results to review or secondary models.
- High-volume batch evaluation, tabular filtering, or programmatic linking across thousands of records or web pages. Use Jev's Score or Choice primitives via lightweight scripts or extensions like duckdb-jev and pg-jev. Sourced benchmarks demonstrate scanning 9,081 records in 13 minutes for $0.32 or executing 8,790 linking decisions across nearly 600 pages for $0.21, avoiding generative text overhead entirely.
- Tasks requiring open-ended text synthesis, dialogue generation, code writing, or multi-step slow-thinking reasoning. Do not route to Jev. Jev is specifically structured as a 'System One Model' limited to three structured outputs (Choice, Score, and Noul) and does not generate conversational text or write code. Direct these tasks to standard generative language models.
Governance turns cheap micro-decisions into a reliable decision plane
Rapid adoption forces operational governance to move at the speed of deployment. According to woshipm, Vercel disclosed on September 18 that nearly 13% of its paid teams adopted Jev within 24 hours of its integration into the Vercel AI Gateway. Jev's 24-hour debut adoption rate on Vercel AI Gateway was double that of the GPT-5.6 series on its launch day and more than six times that of Claude Fable 5.1. Setup takes seconds. As appinn reported, TypeSafe provides $5 in free usage credit upon registration, alongside an agent skill plugin integrated via Claude Code or an npx command.
According to geekpark, developers created nearly 500 open-source projects around Jev within days of its launch. Projects like pg-jev and duckdb-jev immediately brought real-time probability filtering and sorting on database rows using natural language.
When micro-decisions embed directly into data infrastructure, engineering teams must guard against drift by versioning schemas and securing deterministic fallback paths. According to geekpark, one day after Jev launched, a vLLM contributor created an open-source judgment model based on Google's DiffusionGemma with preliminary accuracy close to the official Jev model. Having alternative weights does not eliminate the need for hard guardrails.
Practical implementations treat failure as a routine operating condition. In fast-jev-compaction, woshipm noted that the initial message and the most recent N messages in conversation history are pinned and preserved by default. The system refuses to gamble with unverified pruning. If Jev fails or if compression savings are insufficient, fast-jev-compaction falls back to standard LLM summarization. That escape route prevents silent degradation across agent pipelines.
The mechanics of fast-jev-compaction, an npm library and Claude Code plugin, show how to separate micro-decisions from text generation. Instead of rewriting history, the tool evaluates paired tool calls and tool results with two Jev Noul queries: keepCall and keepResult. User and assistant text remain unedited. Based on keepCall and keepResult probabilities, it executes one of three actions. It can preserve the exchange or delete both entries. The remaining option keeps the call intact while truncating its result.
According to woshipm's author, standard natural-language summarization harms auditability by paraphrasing exact technical details like file paths and stack traces. Retaining raw tool calls avoids that distortion entirely.
Safety bounds complete the pattern. In fast-jev-compaction, the initial message and the most recent N messages in conversation history are pinned and preserved by default. If Jev fails or compression savings are insufficient, the pipeline falls back to standard LLM summarization.
For readers outside China
- Availability: Jev was released on September 15 by TypeSafe AI and opened fully to developers on September 21. It is accessible globally via the Vercel AI Gateway (integrated September 18), through an npx command, and as a Claude Code agent skill plugin. The source material does not disclose any regional lockouts or China-specific restrictions.
- Pricing: TypeSafe AI charges $0.042 per million input tokens, while output tokens are provided free of charge. New user registrations include $5 in free credits. Sourced operational examples range from $0.000015 for a single smart-home sensor check to $0.32 for processing 9,081 product-matching records.
- Closest Western equivalents: Open-source decision model based on Google's DiffusionGemma (developed by a vLLM contributor); Traditional intent recognition models and fine-tuned open-source classifiers; Vercel AI Gateway routing integrations for GPT-5.6 and Claude Fable 5.1
- Data residency: Data residency, server host regions, retention periods, and compliance frameworks (such as SOC 2 or GDPR) are not disclosed in sources.
Sources
- woshipm Jev爆火,具身智能迎来大救星? https://woshipm.com/ai/6468439.html
- appinn Jev 入门:ChatGPT 研究员做了个"不会聊天、不写代码"的 AI 模型,但速度快200倍、成本低400倍 https://appinn.com/jev-getting-started
- woshipm 一万字Jev 工程实践长文:把 Agent 的"判断题"从大模型里拆出来 https://woshipm.com/ai/6467980.html
- geekpark Jev,让全球程序员玩疯了 https://geekpark.net/news/370758
The evidence: 36 facts from 4 Chinese articles
Each line below was extracted from the article it sits under, in Chinese, before any of this was written. The writing is done from these and never from the source prose - that separation is structural, not a promise. How we work.
appinnJev 入门:ChatGPT 研究员做了个“不会聊天、不写代码”的 AI 模型,但速度快200倍、成本低400倍
- ChatGPT researcher Diogo Almeida released an AI decision model named Jev.
- Jev is designed specifically for classification, scoring, and judgment tasks rather than conversational text generation or code writing.
- Jev offers three primary decision formats: Choice for selecting among multiple candidates, Score for rating the degree of a condition, and Noul for binary probabilistic verification.
- Jev returns candidate probabilities and an overall confidence score alongside its decision outputs.
- TypeSafe prices Jev at $0.042 per million input tokens, while output tokens are provided for free.
- TypeSafe provides $5 in free usage credit upon registration for Jev.
- TypeSafe provides an agent skill plugin that can be integrated via Claude Code or an npx command.
- An Appinn tester consumed $0.0008 in API credits during an afternoon of testing Jev.
geekparkJev,让全球程序员玩疯了
- HA-Jev is a Home Assistant plugin that determines whether washed clothes have been left in a washing machine by outputting a probability value without generating text.
- A single judgment by the HA-Jev plugin takes tens of milliseconds and costs $0.000015.
- Former OpenAI researcher Diogo Almeida released Jev, a "System One" AI model that outputs probability judgments instead of generating text.
- Diogo Almeida participated in building ChatGPT and was a co-inventor of Reinforcement Learning from Human Feedback (RLHF).
- Developer Tamara Tran built a Jev plugin for Claude Code that compressed nearly 1 million tokens of context down to 86,000 tokens in 1 second by scoring and filtering historical tool calls.
- The Droidrun team developed mobile-jev, an Android automation agent that navigated the Uber app to the payment interface in 9 steps over 21 seconds using Jev for probability matching instead of generative text models.
- Developers released pg-jev and duckdb-jev on GitHub to perform real-time probability filtering and sorting on database rows using natural language.
- A developer processed 9,081 product-matching records in 13 minutes using a 150-line script powered by Jev, incurring a total cost of $0.32.
- TypeSafe AI prices Jev at $0.042 per million input tokens, while output tokens are free.
- The founder of Distribb used Jev to scan nearly 600 web pages, making 8,790 linking decisions and placing over 500 links within 45 seconds at a total cost of $0.21.
- One day after Jev launched, a vLLM contributor created an open-source judgment model based on Google's DiffusionGemma with preliminary accuracy close to the official Jev model.
woshipmJev爆火,具身智能迎来大救星?
- TypeSafe AI was co-founded by former OpenAI researcher Diogo Almeida.
- TypeSafe AI released the Jev model on September 15 and opened it fully to developers on September 21.
- TypeSafe AI categorized Jev as a 'System One Model' designed specifically to make judgments and decisions without generating text.
- Jev charges $0.042 per million input tokens, while its output is free of charge.
- Vercel disclosed on September 18 that nearly 13% of its paid teams adopted Jev within 24 hours of its integration into the Vercel AI Gateway.
- Jev's 24-hour debut adoption rate on Vercel AI Gateway was double that of the GPT-5.6 series on its launch day and more than six times that of Claude Fable 5.1.
- Jev supports three types of structured outputs within a single API call: Choice, Score, and Noul.
- Jev was trained using Reinforcement Learning from Calibrated Decisions (RLCD) to align its output probabilities with real-world occurrence rates.
woshipm一万字Jev 工程实践长文:把 Agent 的“判断题”从大模型里拆出来
- TypeSafe AI released Jev, a "System One Model" designed to return typed probabilistic decisions rather than generating free text.
- Jev provides three core primitives: Choice for single-choice routing and classification, Score for continuous scoring, and Noul for boolean probabilities between 0 and 1.
- Developers have built Jev demos and integrations for Doom, Mario, browser automation, code review, agent routing, and context compression.
- fast-jev-compaction is a Claude Code plugin and npm library that performs context compression by deciding which tool calls and results to preserve or delete.
- fast-jev-compaction leaves user text and assistant text unedited, modifying only paired tool calls and tool results.
- fast-jev-compaction decomposes context compression into two Jev Noul queries for each tool call: keepCall and keepResult.
- Based on keepCall and keepResult probabilities, fast-jev-compaction executes one of three actions: full retention, retaining the call while truncating the result, or deleting both the call and result.
- fast-jev-compaction falls back to standard LLM summarization if Jev fails or if compression savings are insufficient.
- In fast-jev-compaction, the initial message and the most recent N messages in conversation history are pinned and preserved by default.